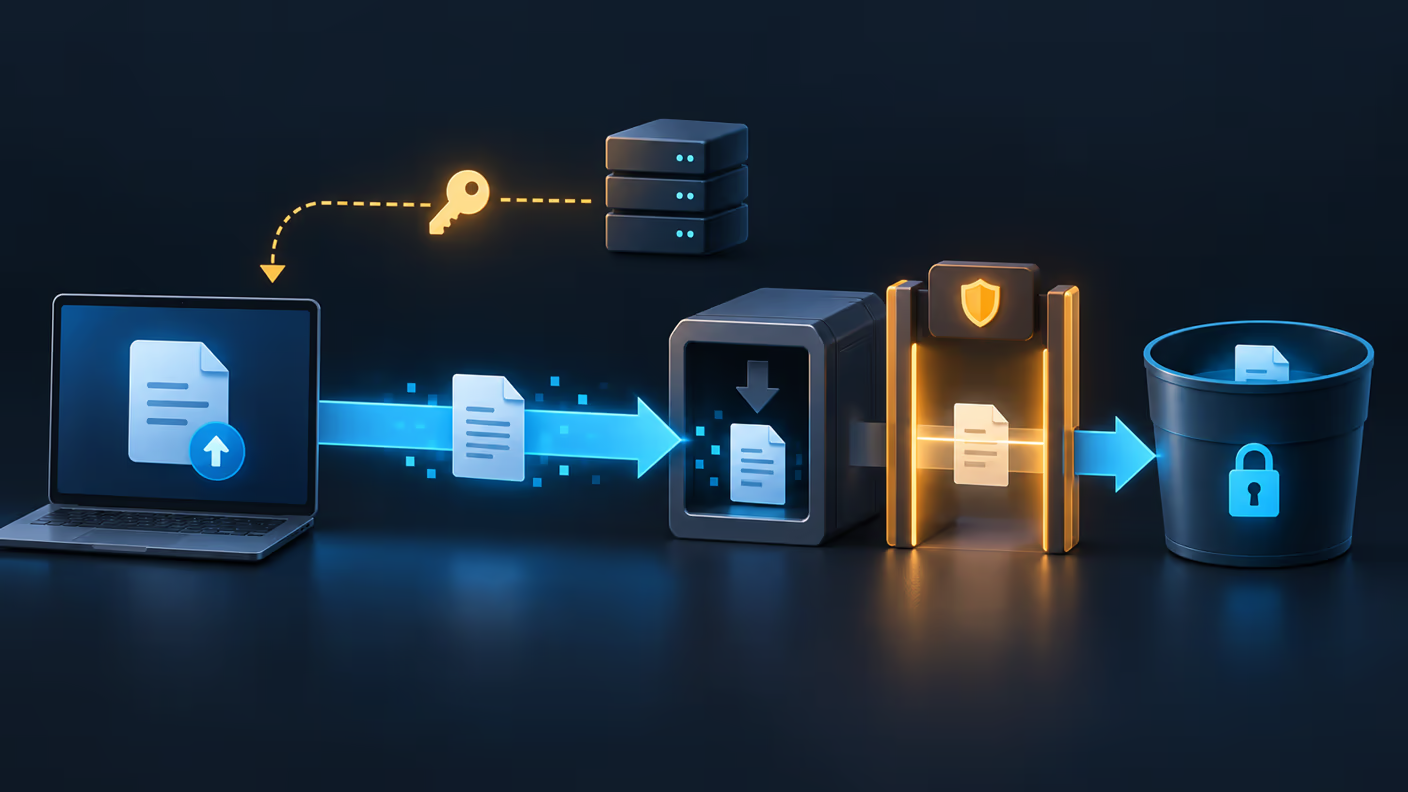
If your upload endpoint receives the file and then forwards it to storage, your server sits in the middle of every byte. Open that route now and find the largest request body it can accept. On AWS Lambda, for example, a synchronous invocation payload is capped at 6 MB, so a customer uploading a larger report hits a wall that has nothing to do with your code.
The fix is to take your server out of the data path. It signs a short-lived URL, the browser uploads straight to storage, and your API verifies the result before anyone can use the file.
How Does a Direct-to-S3 Upload With a Presigned URL Work?
Your server signs a short-lived PUT URL for one specific object key. The browser sends the bytes straight to S3, while your API authorizes the upload and verifies the stored object afterward.
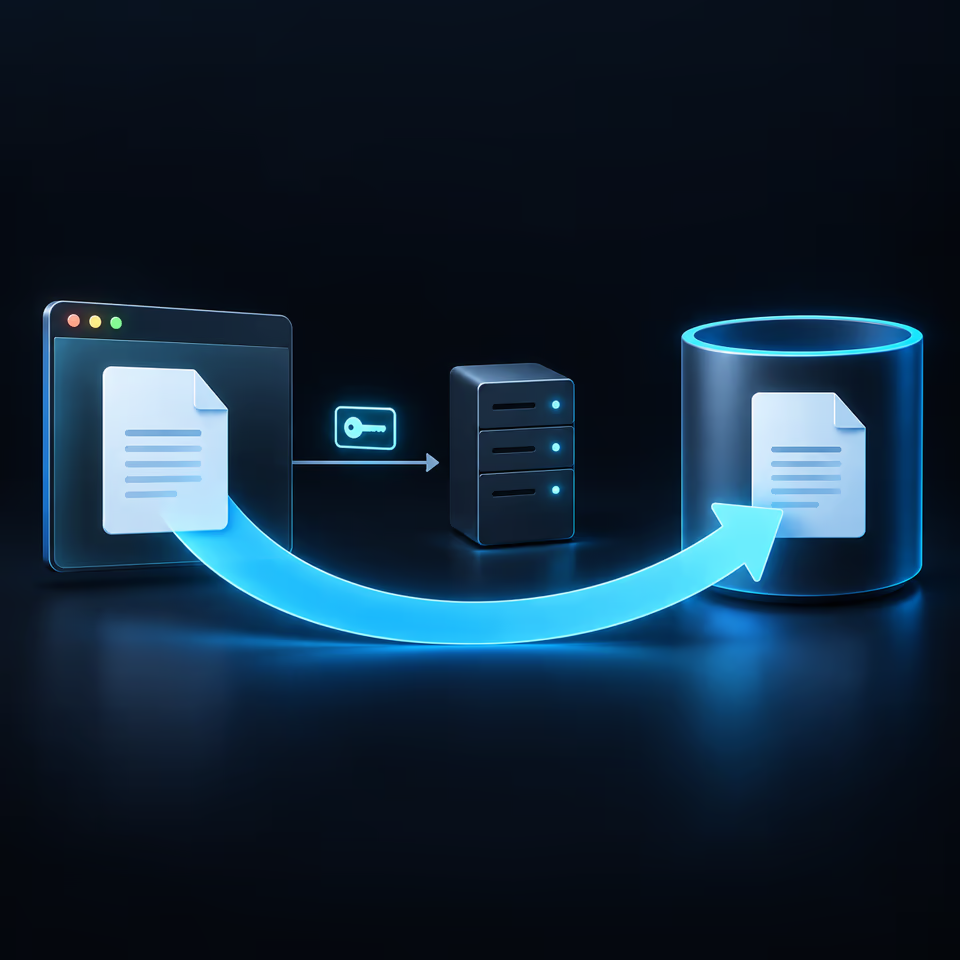
AWS describes it in its presigned URL documentation: you provide credentials, a bucket, an object key, an HTTP method and an expiration, and the URL lets someone upload that specific object without holding AWS credentials. If an object with the same key already exists, S3 replaces it. The flow has five steps:
- The client calls `POST /uploads/request` with the filename, declared MIME type and file size.
- Your API checks that the user is authenticated, the file type is allowed and the tenant is under quota, then builds the object key itself.
- The API returns a presigned PUT URL and an opaque upload ID. It keeps the object key server-side.
- The client PUTs the file to that URL with no AWS credentials.
- The client calls `POST /uploads/confirm` with the upload ID. Your API looks up the key it issued, checks the object in S3 and leaves it unavailable until validation and scanning pass.
The signing step with the AWS SDK for JavaScript v3 looks like this, following AWS's own example:
```ts import { S3Client, PutObjectCommand } from "@aws-sdk/client-s3"; import { getSignedUrl } from "@aws-sdk/s3-request-presigner";
const client = new S3Client({ region: "us-east-1" }); const command = new PutObjectCommand({ Bucket: "my-bucket", Key: key }); const url = await getSignedUrl(client, command, { expiresIn: 900 }); ```
Before marking that upload complete, look up its server-issued key and check the object with S3's HeadObject API. Compare the stored size with your limit, then inspect the actual bytes in the scanning step. A client confirmation, declared file size or stored Content-Type is not proof that the expected file arrived. Keep its database status pending until those checks finish. A presigned PUT URL can be reused before expiry: use a unique key for each upload and don't release an object while that URL can still overwrite it.
For large files, AWS recommends considering multipart upload once an object reaches 100 MB. The documented multipart limits are 10,000 parts per upload, parts of 5 MiB to 5 GiB and a maximum object size of 48.8 TiB. I could not confirm from AWS's presigned URL page that a PUT URL can cap the object size, so check the stored size after upload instead of trusting the declared one.
How long should a presigned URL last?
Short, and never longer than the credentials that signed it. AWS documents that an IAM user's credentials can sign URLs valid for up to 7 days with Signature Version 4, the console allows 1 minute to 12 hours, and a URL made with temporary credentials can't outlive them. Its FAQ gives typical cases: ECS task role credentials rotate every 1 to 6 hours, an STS AssumeRole session lasts 1 hour by default, and EC2 instance profile credentials last about 6 hours at most.
So a URL created with `expiresIn: 86400` from a role session that ends in an hour stops working in that hour, and the failure can look random. For uploads I'd use about 15 minutes as a starting value: that is my recommendation, long enough for slow connections and short enough to limit replay. AWS also treats these URLs as bearer tokens, and S3 checks the expiry when the request is made. A download that started before the deadline continues, but a retry after it fails.
What does the browser need from your bucket?
A CORS rule. S3's CORS configuration takes allowed origins, methods and headers, and the origin can be `*` or a specific origin such as your own domain, with at most one wildcard in the string. Use your exact domain for production and list only `PUT` for the upload bucket.
What Should Happen After the File Lands?
Keep new uploads in a quarantine prefix or bucket, validate and scan them with an S3-triggered function or a managed scanner, and only then move them to where users can read them.
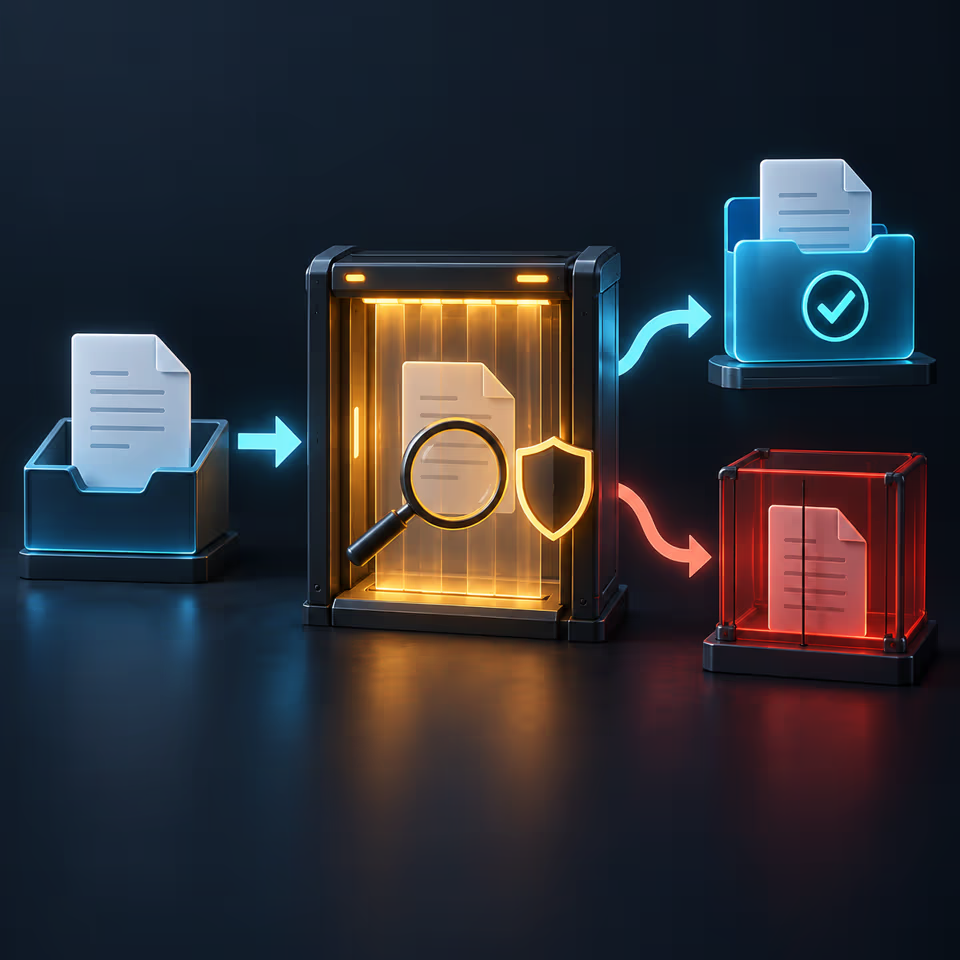
Treat every upload as untrusted until your checks pass. A filename, extension and Content-Type all come from the client; none establishes what the file contains.
The pipeline I'd build has three locations: `incoming/`, `clean/` and `quarantine/`. Presigned URLs always write to `incoming/`. An S3 event notification triggers your checker. According to AWS's event notification documentation, notifications are designed to be delivered at least once, usually within seconds but sometimes a minute or longer, so the checker must be safe to run twice and your UI must tolerate a delay. AWS also warns that a function that writes to the bucket that triggers it can loop, and suggests separate buckets or a trigger limited to the incoming prefix.
Run the cheap check first. MIME validation reads the file's magic bytes instead of trusting the `Content-Type` header or the extension, using a library such as `file-type` for Node or `python-magic`. A mismatch is grounds to quarantine without spending compute on a virus scan. Matching magic bytes are only a format check, not a malware verdict.
| Scan option | What it is | Constraint to check |
|---|---|---|
| ClamAV in a function or container | Open-source (GPLv2) antivirus toolkit you run yourself | Lambda has a 15-minute timeout, 512 MB to 10,240 MB of `/tmp` and a 10 GB container image limit |
| GuardDuty Malware Protection for S3 | Managed scanning of newly uploaded objects | Results go to EventBridge and CloudWatch, with optional object tagging |
Those Lambda limits come from AWS's quotas page. They suggest that scanning very large files in Lambda needs a container or a managed service, which is my reading of the limits, not an AWS statement.
Add one housekeeping rule. An S3 lifecycle expiration rule on `incoming/` removes objects that your checker never processed, for example after a timeout. AWS notes that S3 queues expired objects for removal and removes them asynchronously, so expect a delay.
How Do You Isolate Tenants' Files?
Put the tenant ID as the first path segment of every object key, set that key on the server, and enforce the prefix in a storage policy so one tenant cannot read or write another's folder.
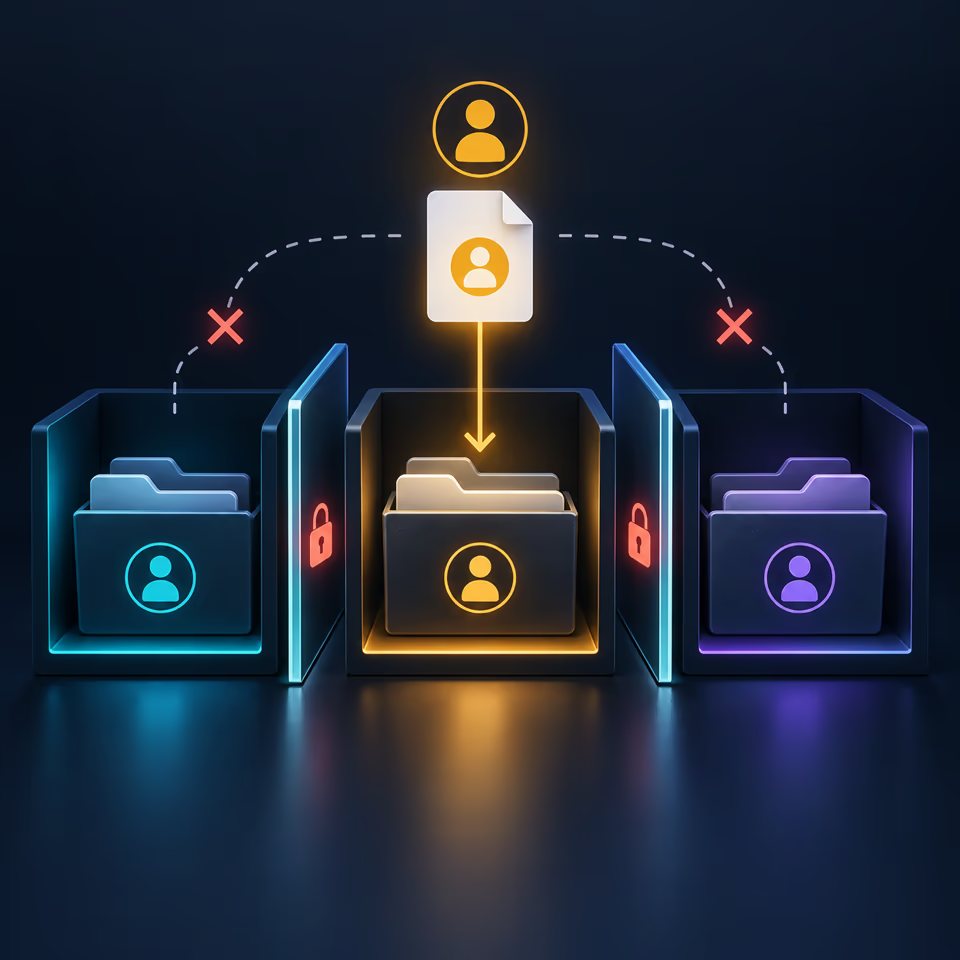
With Supabase Storage, this is one policy. Supabase's access control guide says the only policy required for uploading is an `INSERT` permission on `storage.objects`, and it shows `storage.foldername(name)` for folder checks:
```sql create policy "Tenant folder isolation" on storage.objects for insert to authenticated with check ( bucket_id = 'uploads' and (storage.foldername(name))[1] = (select auth.jwt()->>'org_id') ); ```
This assumes your auth setup adds an `org_id` claim to the JWT. A user in org `abc123` then can't insert `org456/report.pdf`, because the policy rejects it. Overwriting with upsert needs `SELECT` and `UPDATE` policies as well. The same guide says the service key bypasses RLS entirely and belongs only in trusted server code. Supabase Storage also offers an S3-compatible API that supports presigned URLs and multipart uploads, and its file size limit can't exceed 50 MB on the Free plan but can be set up to 500 GB on Pro and above. See the React and Supabase RLS stack and the row-level security glossary entry for the database side.
On raw S3, your API controls the key. Build `{orgId}/{uuid}/{filename}` on the server and never accept a prefix from the client. For multi-tenant SaaS with contractual isolation needs, a bucket per tenant gives separate access logs and removes the risk of one misconfigured policy exposing everyone, at the cost of more buckets to manage. For most B2B products, prefixes are a reasonable default. That is a recommendation, and the multi-tenant architecture post covers the trade-offs.
The Callidus case study describes the same principle at the database layer: Firestore data lives under `tenants/{tenantId}/`, and JWT claims carry the tenant ID and role. It doesn't describe file storage, so take it as an analogy. The BookBed case study covers a Flutter, Firebase and Stripe stack rather than S3, so this pattern is portable advice, not something either project documents.
How Should You Serve Files and Image Variants?
Keep the bucket private. Only after an upload passes validation and scanning should you hand out short-lived signed GET URLs; use an image service for variants so originals never need to be public.
A public bucket means anyone who learns an object key can read the file, and in a B2B product that could be another customer's quarterly report. Generate a signed GET URL when a user asks for a file and expire it after minutes to an hour. The credential rule from earlier applies here too: if a role session signs the URL and your frontend caches it, the URL can die mid-session, so refresh on a 403 instead of caching for a whole session.
Cloudflare R2 is an alternative with the same signing model. Its presigned URLs support GET, HEAD, PUT and DELETE, last from 1 second to 7 days, and work only on the S3 API domain, not custom domains. They don't support POST multipart form uploads, and you should set CORS rules for browser use.
For thumbnails and previews, Cloudflare Images lists $5 per 100,000 images stored per month and $1 per 100,000 delivered on the paid plan, plus $0.50 per 1,000 unique transformations after the first 5,000. imgproxy is the self-hosted option: a Go server that resizes images on the fly from parameters in the URL, with an open-source edition and a paid Pro version. Prices change, so confirm them before you budget. If you run serverless, weigh the ops cost of hosting imgproxy against a per-image fee.
Keep credentials out of the browser as well. The post on secrets management and API key security covers where signing keys should live, and the SaaS MVP stack guide shows how storage fits the wider architecture.
What does your upload route do with the bytes today? If they still pass through your API, list the file sizes you need to support this quarter and compare them with your platform's payload limit. That single comparison tells you whether moving to presigned URLs is a cleanup or a necessity.